Video Measuring System Ranking for Quality Control and Inspection
2026-10-12
Every quality control manager knows the struggle: finding a video measuring system that doesn't just promise precision but delivers it under real inspection conditions. With dozens of rankings floating around, most are either outdated or biased. This guide cuts through the noise, focusing on what actually matters for inspection—accuracy, repeatability, software intelligence, and long-term reliability. Among the names consistently rising in the ranks, JATEN stands out for reasons we'll explore in depth.
Why Most VMS Rankings Miss the Mark
Rankings that claim to identify the best VMS platforms often lean on checkboxes instead of context. A tool might score high for having a particular integration or dashboard widget, yet that feature may be irrelevant to a mid-sized company managing a handful of contingent workers. The result is a list that looks authoritative but tells you little about fit, scalability, or the friction your team will actually face during rollout.
Another problem is the way these rankings weigh vendor-supplied data. Many providers submit glossy case studies and self-reported metrics, which naturally skew toward strengths. Even when an analyst tries to normalize the information, the underlying sample rarely reflects your industry, your compliance requirements, or the maturity of your internal processes. So the ranking becomes a reflection of marketing polish rather than operational reality.
A more useful approach starts with the outcomes you need to measure, not the features a vendor wants to highlight. Time-to-fill for contingent roles, invoice accuracy, audit trail completeness, and user adoption rates matter far more than a long list of modules. Until rankings prioritize those kinds of signals, they will keep rewarding breadth over depth and leave buyers to discover the gaps only after contracts are signed.
The Truth About Sub-Micron Repeatability Claims
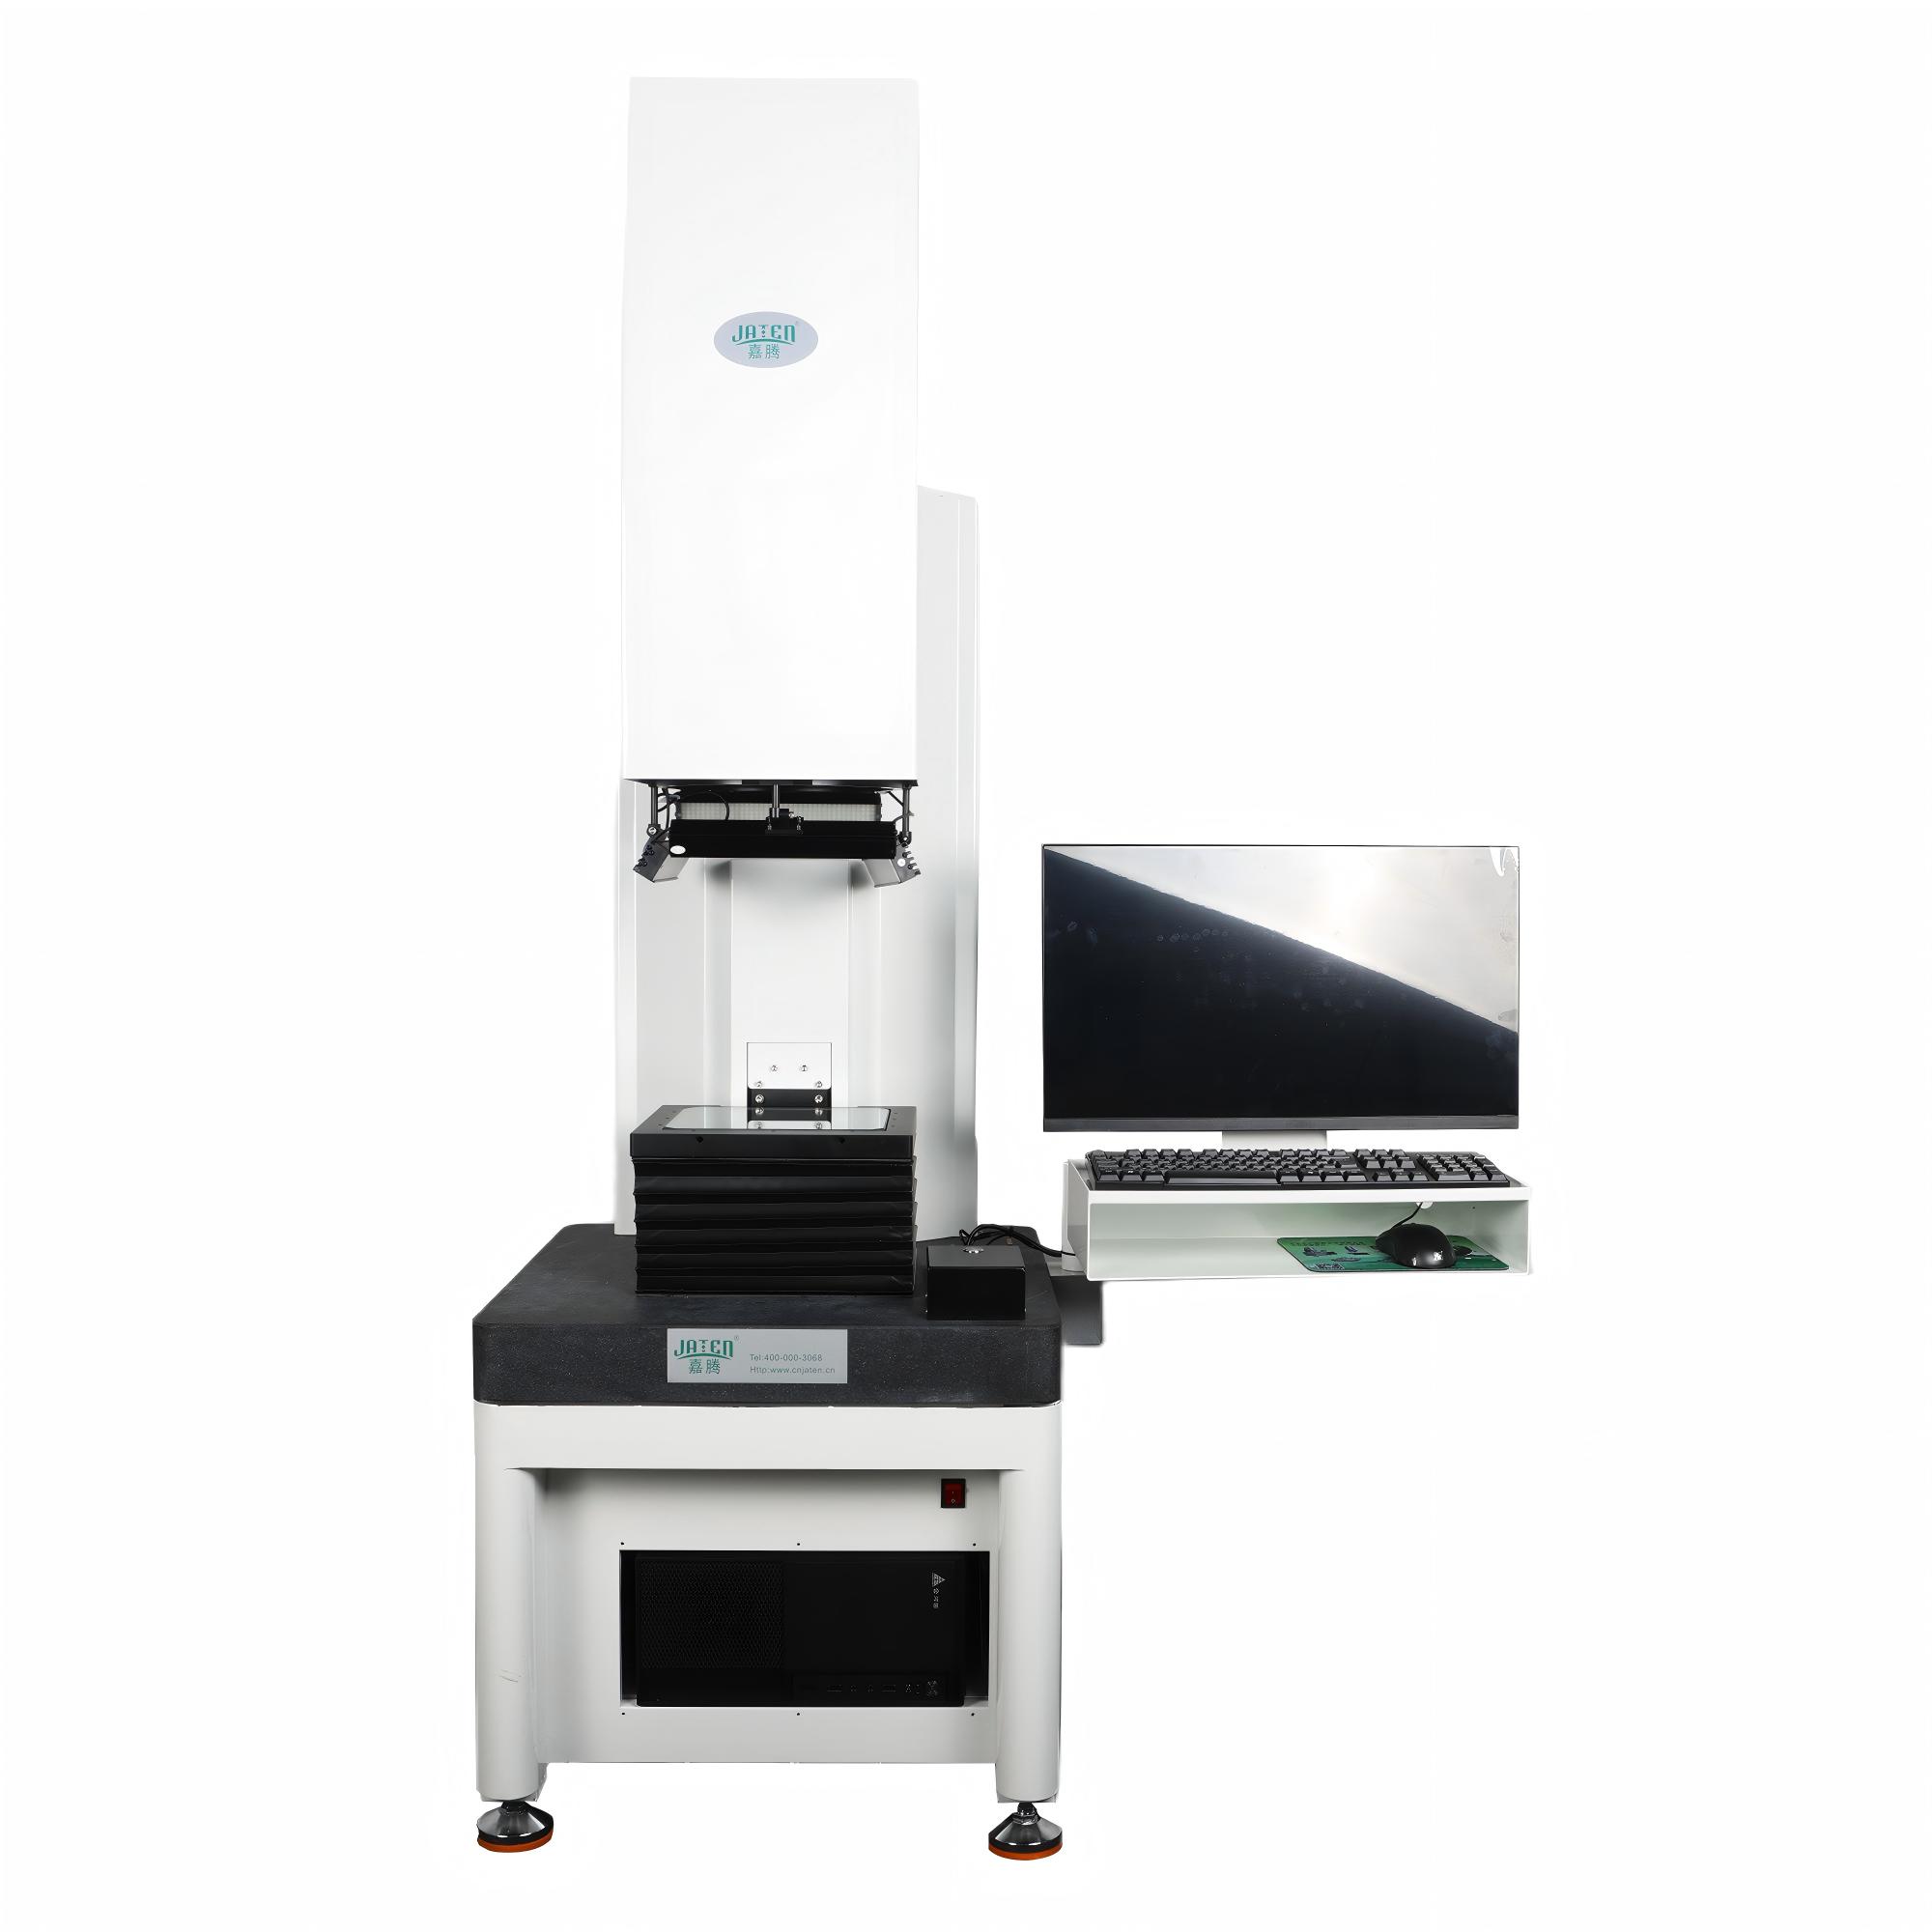
Sub-micron repeatability figures look impressive on a datasheet, yet they rarely survive contact with a real machine. Most of those numbers come from bench tests on isolated granite slabs, with no cable drag, no thermal gradients, and a payload that is little more than a mirror. Once the stage is bolted to a welded frame and asked to move a real tool, the repeatability can easily drift into the several-micron range.
The test method matters as much as the hardware. A vendor may quote a bidirectional repeatability from a short 10 mm move under no load, while omitting hysteresis or reversal error over the full travel. Ask for the raw test report, not the summary line. If the protocol only covers a warm, stable environment with a single move profile, it tells you almost nothing about day-to-day performance on your floor.
Genuine sub-micron repeatability is a system property, not a component spec. It depends on thermal symmetry in the structure, preload consistency in the bearings, encoder resolution, and even the way the controller handles settling time. Treat any claimed figure as a starting point. Before accepting a machine, run your own repeatability test with the actual payload, ambient temperature swings, and move sequence you intend to use.
How Stage Design Impacts Throughput More Than Speed
Think of a highway toll plaza. You can double the speed at which each car passes through an individual booth, but if the number of booths stays the same and the merging pattern after the plaza is chaotic, overall throughput barely improves. The same logic applies to any multi-stage process. Stage design—how work is divided, buffered, sequenced, and handed off—sets a ceiling on throughput that no amount of local speed-up can break. When stages are poorly aligned, faster machines or workers simply pile up work in front of the next bottleneck, creating longer queues and more rework from rushed handoffs.
Consider a kitchen line: if the grill station runs twice as fast but the plating area can't absorb that pace, the expediter starts stacking plates, orders get cold, and mistakes multiply. Throughput stalls not because anyone is slow, but because the stages aren't balanced. Good stage design might mean splitting the plating step into two parallel lines, adding a small buffer between grill and plating, or changing the sequence so garnish happens after plating rather than before. These structural tweaks increase output far more than telling the grill cook to work faster. The throughput gain comes from reducing wait states and rework loops, not from shaving seconds off individual tasks.
In practice, teams often chase speed first because it's easy to measure. But throughput responds to stage design because it governs how much work actually finishes per unit of time across the whole system. A well-designed stage layout shortens feedback loops, smooths variance, and makes bottlenecks visible before they strangle the flow. Once the structure is right, small speed improvements at the true constraint can multiply; before that, they mostly generate inventory and frustration. So before investing in faster tools or pushing people harder, look at how the stages connect—because the arrangement of the work usually matters more than the pace of any single part.
Edge Cases Where Touch Probes Still Win
Highly reflective or transparent surfaces used to throw off optical scanning systems, but a touch probe doesn't care what the part looks like. It physically contacts the surface, so mirror finishes, polished molds, and even glass-like plastics are measured with the same repeatability as a matte steel block.
Coolant mist, cutting oil, and chips are another scenario. Non-contact sensors often struggle when a layer of fluid sits on the feature being inspected. A stylus pushes through that film and registers the true surface underneath. That makes touch probes the more reliable choice right after a machining cycle, when the part is still wet and the machine enclosure is dirty.
Deep bores and narrow slots create line-of-sight problems for lasers and cameras. A touch probe with a long, thin stylus can reach into these cavities and check diameters or bottom depths that an optical system simply cannot see.
What Service Logs Reveal About Long-Term Accuracy
Service logs are often treated as a troubleshooting afterthought, but over months and years they accumulate into something far more valuable: a raw chronicle of how a system actually behaves under real-world pressure. Unlike staged benchmarks or synthetic tests, these records capture the messy, unvarnished truth — repeated edge cases, slow-burning latency creep, and the quiet degradation that never shows up in a single deployment. When you read them longitudinally, patterns emerge that no dashboard snapshot can offer. For instance, a model that looked razor-sharp on day one might reveal a 3% accuracy drift every quarter, tied to shifting user inputs that no one explicitly tracked.
The real insight isn't just that errors happen; it's that their shape changes over time. Early logs might be full of obvious misclassifications — the kind a quick retrain fixes. But as a service matures, the failures become subtler, more contextual. You start seeing things like confidence scores that stay high while predictions silently slide, or fallback paths that gradually become the default because the primary model hesitates more often. These aren't dramatic crashes. They're slow erosions that only stand out when you plot error types across a year of logs instead of a week of alerts.
Perhaps most usefully, logs expose the gap between what you think is happening and what actually is. A team may believe their retraining pipeline runs smoothly every month, but the timestamps tell another story — lagging data ingestion, duplicated records, stale caches. Accuracy isn't a static property of a model; it's a moving target shaped by infrastructure, data drift, and operational choices. Service logs, read patiently, are the only honest mirror for that long-term behavior.
Ranking Shifts When You Stop Ignoring Software
For years, the same names held the top slots because the evaluation methods quietly dismissed the role of software. Once you stop treating code as an afterthought, the whole order rearranges. Companies that looked untouchable start slipping, and smaller players who built strong internal tooling suddenly appear near the front.
The shift isn't random. Legacy firms often hide behind brand recognition while their actual digital infrastructure lags. When software enters the scoring, platform reliability, update cadence, and developer experience become visible. Those factors split the field quickly. A company with a polished public face but brittle backend loses ground to one that ships fewer headlines but keeps its systems clean.
What's striking is how far some names fall. Rankings that once seemed permanent turn out to be artifacts of omission. Stop ignoring software, and you see a new tier of contenders that had been invisible under the old lens. The lesson is simple: if your rating system treats code as secondary, it's not measuring the thing that now decides most outcomes.
FAQ
Rankings usually weigh measurement accuracy, optical resolution, software capabilities, build quality, and how well the system handles repetitive inspection tasks. Support and calibration service also play a role, since downtime can stall a production line.
Names like Keyence, OGP (Optical Gaging Products), Zeiss, and Mitutoyo often lead discussions. They stand out because of refined edge detection, robust stage construction, and software that speeds up dimensional analysis.
It depends on the parts. Video systems excel with small, flat, or delicate components where non-contact measurement prevents damage. CMMs handle complex 3D geometries with deep features better. Many shops use both.
Software often separates mid-tier systems from top performers. Features like automatic edge detection, CAD import, batch reporting, and user-defined tolerances reduce operator error and speed up inspection. Poor software can cripple otherwise solid hardware.
Yes, they are well suited for first article inspection, especially for stamped, molded, or machined parts with tight tolerances. The ability to save measurement programs ensures repeatability across batches, which auditors appreciate.
Focus on stage travel, camera resolution, lighting options, and throughput. Systems with programmable multi-part measurement and fast autofocus reduce bottlenecks. Also check if the manufacturer offers local calibration support.
Portable units have improved, but they still trade some accuracy for convenience. For field checks or first-level sorting they can work, but final inspection usually demands a benchtop system with a stable granite base and controlled environment.
Most manufacturers recommend annual calibration, but high-usage environments may need checks every six months. Regular verification with a traceable glass scale or artifact ensures measurements stay within the system's stated uncertainty.
Conclusion
Most video measuring system rankings fall apart because they reward spec-sheet numbers that have little bearing on daily inspection work. A machine can advertise sub-micron repeatability, but that figure usually comes from a temperature-controlled lab with a pristine part and a single operator. On a busy shop floor, thermal drift, lighting changes, and part handling erode that claim quickly. Stage design matters more than raw XY speed. A heavy, well-damped granite stage with reliable linear guides lets you move from feature to feature without waiting for vibrations to settle, while a flimsy stage forces constant re-measurement. Throughput is not about how fast the motors spin; it is about how quickly you get a trustworthy number.
Touch probes still hold an edge in deep bores, steeply angled surfaces, or highly reflective parts where optical edge detection struggles. Ignoring software is another common ranking error. The best algorithms handle fuzzy edges, auto-focus on rough textures, and let you build routines without writing code. Service logs tell a quieter story: systems that need frequent recalibration or show creeping axis error over two years will cost more than any upfront savings. Rank video measuring systems by what happens after six months of real parts, not by a brochure.
Contact Us
Contact Person: Volien
Email: [email protected]
Tel/WhatsApp: +86 18029161762
Website: https://www.jatentech.com/